AI memory design
Does AI forget what it stops searching?
By The Konshus Team
The short answer
An AI can keep information in storage yet effectively leave it out if its retrieval process repeatedly favors other records. This is a proposed engineering analogy to human retrieval-induced forgetting, not evidence that AI searches suppress memories the way a human brain does.
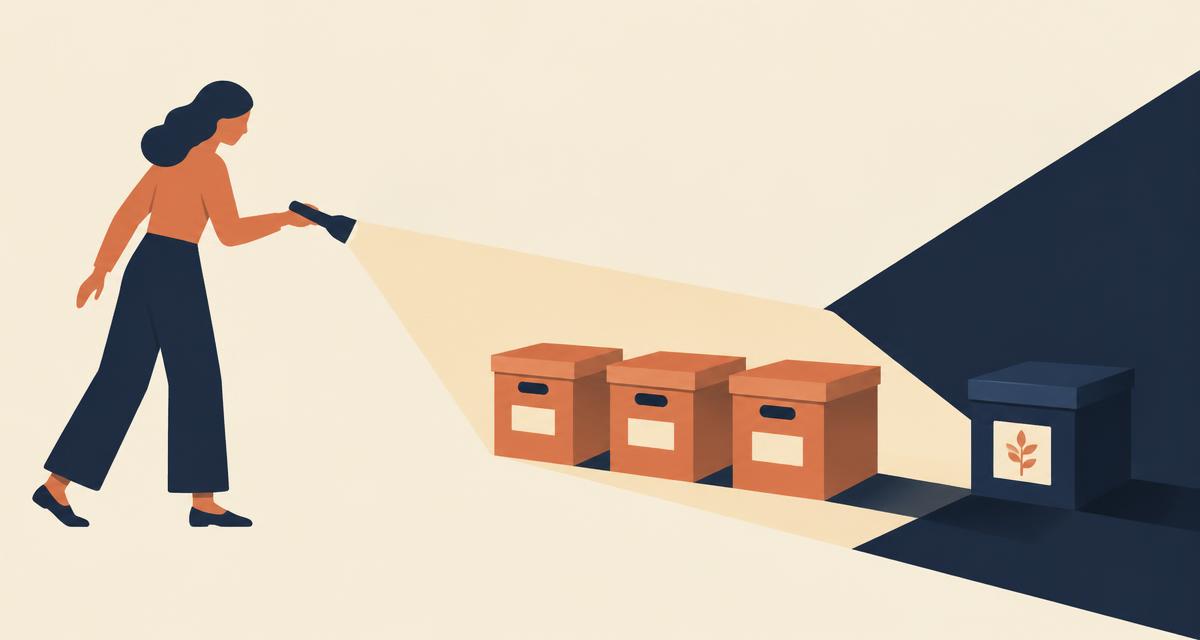
Imagine asking a personal assistant what kind of work suits you. It finds several accounts of successful business launches and recommends entrepreneurship. Later, it retrieves the same experiences when you ask about your strengths. Eventually, every career conversation starts from the same polished account.
But your archive also contains enjoyment of teaching, satisfaction from mentoring, and doubts about leading another company. Nothing has been deleted. The assistant simply keeps looking elsewhere. This is a hypothetical failure mode, not a reported finding. It raises a practical question: can a system preserve your records while gradually narrowing the evidence it uses to describe you?
What can human forgetting research tell AI designers?
Human retrieval-induced forgetting is a starting point, not a ready-made explanation for computers. Reading a database record does not spontaneously inhibit another record. But ranking rules could repeatedly favor a familiar summary while leaving a relevant original passage unseen. The analogy concerns the outcome of selection, not shared biology.
The design question is whether repeated retrieval changes future retrieval priorities in ways that make useful evidence increasingly difficult to surface.
How could accurate memories produce a narrow answer?
If appearing in an answer increases a record’s future priority, familiar evidence becomes easier to retrieve, and being retrieved makes it more familiar still. The resulting account can be coherent and supported by genuine evidence while still missing important counterexamples.
Derived summaries create another loop. If several summaries restate the same original experiences and the system treats them as independent confirmation, repetition looks like growing evidence when the support has not changed. A design proposal is to link summaries to their sources, distinguish repeated mentions from independent support, and deliberately search for relevant counterexamples.
What are the three different meanings of AI forgetting?
Storage loss means the original information is unavailable because it was deleted, corrupted, or never captured. Retrieval failure means a record remains available but does not reach the assistant’s working evidence. Answer-level omission happens after retrieval: the assistant receives relevant information but leaves it out or dismisses a conflict.
These distinctions locate the repair. Was the record captured? Could search find it? Did the answer reflect it? Evaluation should examine the whole path from preserved source to final conclusion.
How could we test for a retrieval feedback loop?
A proposed experiment could use synthetic life archives with identifiable sources: repeated successes, rare but meaningful experiences, changing preferences, and later corrections. Two otherwise identical systems would differ in retrieval policy—one reinforcing frequently used memories, the other limiting circular reinforcement and searching for overlooked evidence.
Early questions would invite familiar material; later questions would require evidence never previously selected. Measures would include support from original sources, recovery of rare information, diversity of independent evidence, sensitivity to corrections, and cost. This is a proposed experiment, not an obtained result.
Should a personal AI preserve everything in the foreground?
No. Preserving a source and foregrounding it in every answer serve different purposes. A digital archive can keep original evidence while adjusting what receives immediate retrieval priority. Lower priority need not mean destruction.
The goal is neither endless searching nor maximum repetition. It is relevant coverage and conclusions proportionate to the evidence. A personal memory system should be able to use a familiar account while remaining capable of finding the parts that account leaves out.
What does this look like for a person using AI memory?
Picture someone who has told an assistant about their job, their hobbies, and a health goal over many months. If search keeps surfacing the job, answers may start to feel as if work is the whole person. Nothing was deleted; the other records simply stopped being chosen.
A useful habit for anyone relying on AI memory is to ask directly about less common topics now and then, and to check whether the answer reflects what they actually said. If the system cannot find something you know you shared, that is a sign of a search gap, not proof the information is gone.
For builders, the same scene suggests a simple check: periodically measure which stored records have not appeared in any answer for a long time, and test whether they still surface when a question clearly calls for them.
In one sentence
- Retrieval failure
- A failure to surface relevant information that remains available in storage.
- Answer-level omission
- A failure to use relevant evidence appropriately after the system has retrieved it.
- Source independence
- The distinction between genuinely separate supporting records and multiple summaries derived from the same original evidence.
Key takeaways
- Stored information can still be absent from retrieval or from the final answer.
- Repeated summaries should not be mistaken for independent supporting sources.
- Synthetic archives could test whether retrieval habits obscure rare but important evidence.
- The AI comparison is an engineering hypothesis, not a demonstrated humanlike forgetting mechanism.